 cartesia.ai/blog/from-tokens-to-bytes-part-1
Scaling Hierarchical Networks
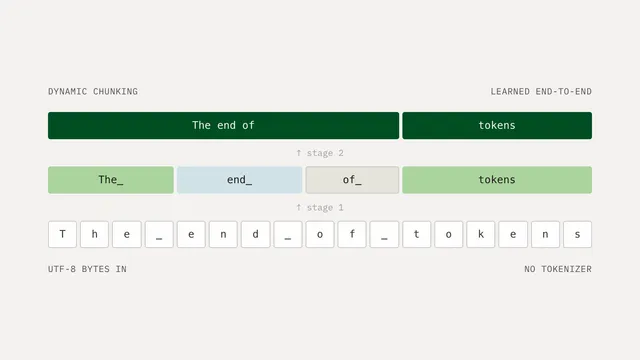
The post presents scaling-law results for hierarchical networks (H-Nets), which learn chunking directly from bytes instead of using tokenizers. It reports 1-stage H-Nets giving compute gains of up to 3-5x over BPE Transformers, and a 2-stage model beating an open-source baseline with 10x less compute and data.
