A blog post tests a recent paper's claim that language models can infer a neural network's function from raw weights without tools. Running Qwen 3.8 27B locally, the author reports it identified Pac-Man, Pong, and Breakout from prompts but failed on Freeway, while noting skeptics dispute parts of the paper.
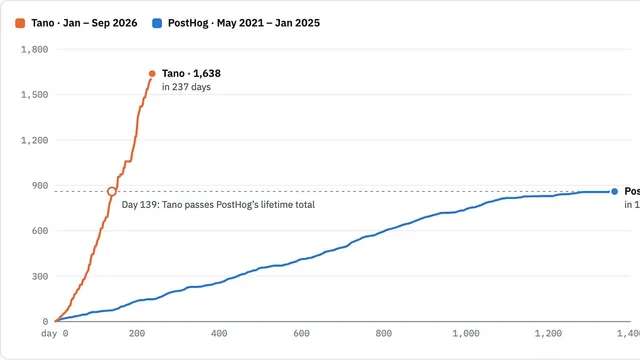
Software engineer Neil Kakkar reports about 11 times more monthly PRs at AI-native startup Tano than at PostHog, which he treats as a pre-AI baseline. He describes coding agents changing review and collaboration, while noting trade-offs such as optional human code review.
Debian's DFSG, Licensing & New Packages Team has begun using LLMs to draft reviews of packages in the project's new queue, after an August vote favored responsible generative AI use. The practice has drawn objections and questions about where limits on LLM output should be set.
Meta's F3 Lightning decouples ads ML feature releases from shared execution, so features compile, validate, deploy, and roll back independently. It preserves efficiency with stable IDs, one execution plan, a shared memory buffer, and dense indexing; comparable features reach production 3.6x faster without added compute cost.
Vitest 5.0, a Vite-native testing framework from VoidZero, reports roughly 8–25% speed gains across most benchmark setups, with VM pools up to 53% faster. The release adds a Trace View and stricter defaults, requires Vite 6.4 and Node.js 22.12, and changes CI artifact paths to one .vitest/ directory.